Git Rebase vs Merge: When to Use Each (2026 Rules)
Mahmud Hasan
October 28, 2026
Git rebase vs merge when to use is one of those questions with a short answer that everyone nods at and then ignores in practice: rebase your own branch, merge everyone else's. The confusion survives because both commands can produce the same files. They differ in what they do to history, and history is the part your future self has to read.
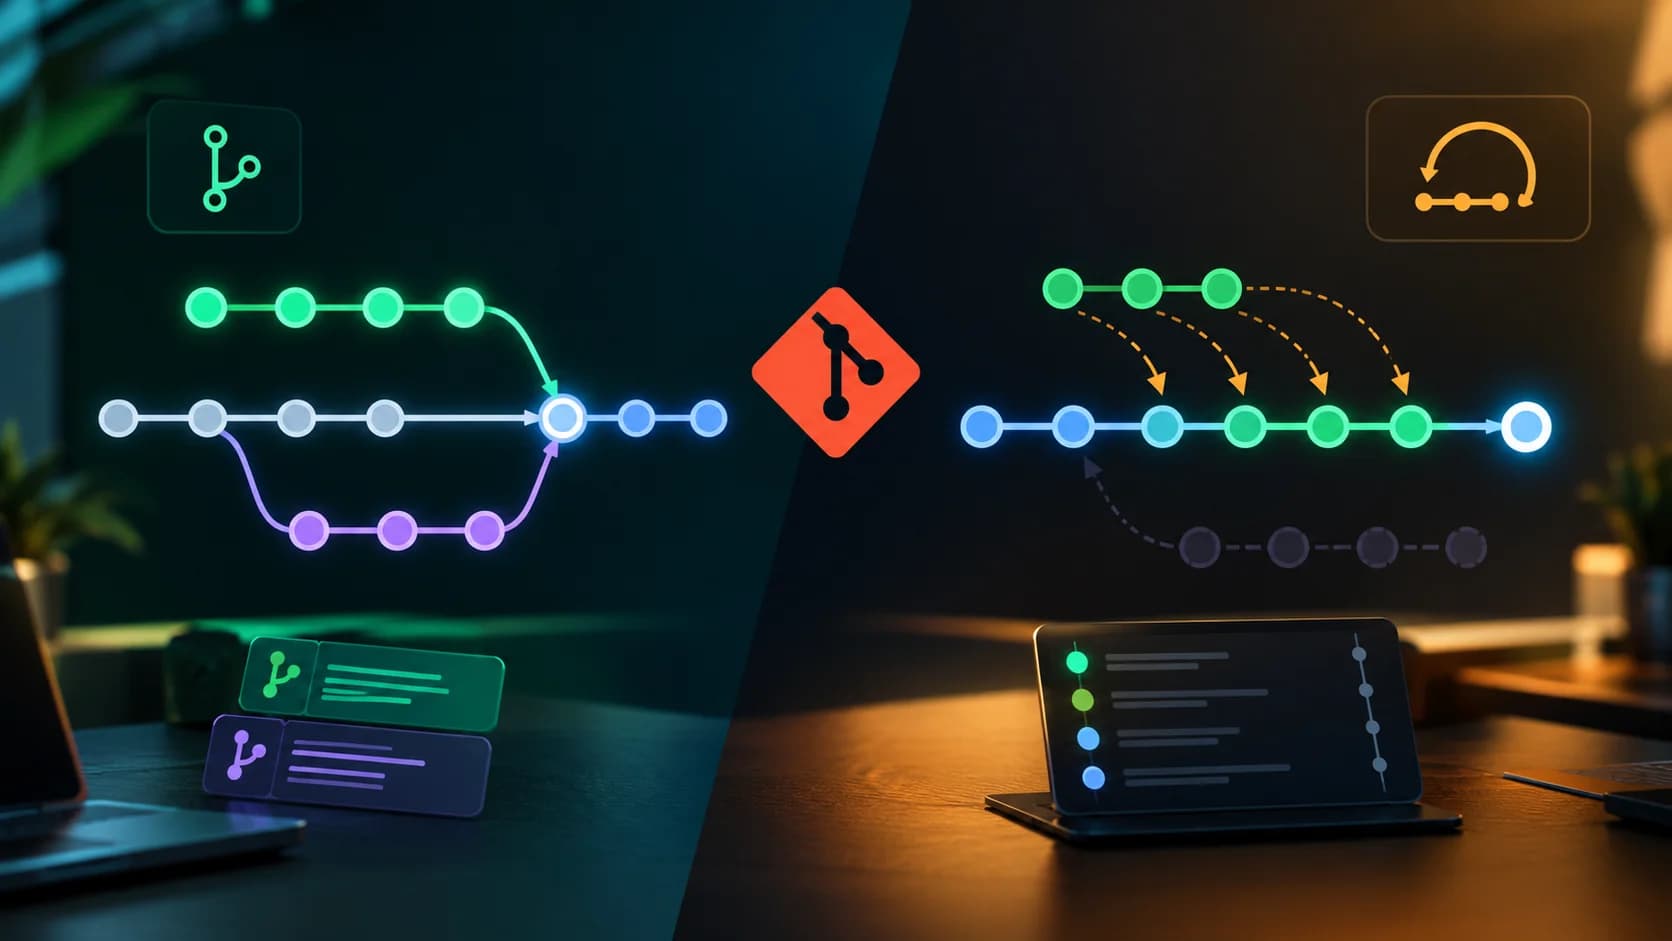
I ran both paths on the same toy repository before writing this. One branch, one commit, main moved once. Merge produced a merge commit with two parents. Rebase produced a straight line — and, critically, a different commit hash for the same change: the original feature commit was e296a39, and after rebasing it became e8a9528. Same message, same diff, new identity. That single fact explains nearly every rebase disaster story you have heard.
What merge does: it records the join
Merge takes two histories and ties them together with a new commit that has two parents. My test graph looked like this:
* afbb521 Merge main into feature-merge |\\ | * 238a122 Update main * | e296a39 Add feature |/ * 469a3f9 Add app skeleton
Nothing is rewritten. The feature commit keeps its hash, main keeps its commits, and the merge commit permanently records when the two lines met and where each came from. That record is merge's real advantage: when you later ask "which release included this feature?" or "when did this branch land?", the answer is a commit you can point at, not a story you reconstruct from dates.
Merge's cost is readability at scale. A team that merges often, in both directions, ends up with a graph that reads like a subway map, and git log interleaves parallel lines of work. That is annoying, not dangerous. Merge is the safe default: you can merge a branch you do not fully understand and the worst outcome is an ugly graph.
What rebase does: it replays your work as if you started later
Rebase sets your commits aside, moves your branch to the tip of the target branch, and re-applies each commit one by one. My test graph after git rebase main was a straight line:
* e8a9528 Add feature * 238a122 Update main * 469a3f9 Add app skeleton
It reads as if you had simply started your feature after main's latest change. Reviewers love this: a pull request that rebases cleanly shows one logical sequence instead of a braid, and git bisect walks a line instead of a tree. Interactive rebase (git rebase -i) extends the same idea to cleanup — squash the three "wip" commits into one, reword the vague message, drop the accidental debug commit — before anyone else ever sees the branch.
The price is the hash change. Because a commit's identity includes its parent, replaying onto a new parent creates a new commit; the old one is orphaned, recoverable from the reflog for a while but on no branch. On a branch only you have touched, that is tidying. On a branch your teammates have pulled, it is rewriting commits they have already built on — their local copies no longer match yours, and reconciling the two histories is the mess the golden rule exists to prevent.
Git rebase vs merge: the one rule that decides it
Ask one question before either command: has anyone else based work on this branch? If the answer is yes — it is main, a release branch, or a feature branch a teammate has pulled — merge. If the answer is no — it is your local branch, or a branch you pushed only as a backup and nobody else has pulled — rebase freely. That is the whole decision procedure, and most teams that argue about rebase versus merge are actually arguing about whether a branch counts as shared.
Two corollaries follow. First, never force-push a shared branch to "fix" a rebase; if you must force-push your own feature branch after rebasing it, use --force-with-lease, which refuses if someone else pushed since your last fetch — it turns a silent overwrite into a loud stop. Second, the branch you deploy from is shared by definition: it is the branch your production system, your teammates, and your rollback plan all point at, so it is merge-only even if you are the only person committing to it today. The same reasoning applies to the main branch in a deployment workflow: the deploy target must never be rebased, because every deploy is a claim about exactly which commits are live.
One practical note: rebase refuses to start with a dirty working tree. If you have uncommitted changes when you want to rebase, stash them first rather than committing a half-finished state just to clear the way — the stash fixes cover the cases where that step itself goes wrong.
The workflow most teams actually land on
The rebase-versus-merge debate usually resolves into a hybrid, and it is a good one: rebase locally, merge at integration. While a feature is yours, rebase it onto main often, so conflicts arrive one commit at a time while each change is still fresh in your head. Clean it up with interactive rebase. Then merge it into main — many teams use --no-ff so the merge commit survives even when a fast-forward would be possible, preserving the "this feature landed here" record that merge is good at.
For pulling updates, git pull --rebase applies the same logic to the fetch step: your commits replay on the remote tip instead of gaining a merge commit every sync. Set it per-branch rather than globally if you work across teams with different conventions — it is still a rebase, safe only on branches nobody else is standing on.
Edge cases where the simple rule bends
Long-running branches are where merge earns its keep twice over: rebasing a month-old branch replays dozens of commits and can surface the same conflict repeatedly, while a single merge resolves everything once at the join point. If a rebase conflict reappears in every replayed commit, the branch lived too long or the commits are too coarse — fix the workflow, not just the conflict.
Audit trails bend the rule toward merge as well. In regulated work, or anywhere a release note must trace a feature to an integration event, the merge commit is evidence; a rebased linear history shows what shipped, not when branches joined. Squash merging is the middle path some teams choose — one clean commit per feature on main — but it discards the feature branch's internal history entirely, so it suits small features better than large ones where the step-by-step story matters for later debugging.
And if a rebase goes wrong, do not improvise. While it is still running, git rebase --abort returns the branch to where it started. After it finishes, the reflog still holds the pre-rebase position (ORIG_HEAD immediately after, or the reflog entry from before), so a bad rebase is recoverable — the damage people fear comes from force-pushing the rewritten history to others, not from the rewrite itself.
What to do this week
Pick the rule, then write it down where your team can see it: private branches rebase, shared branches merge, deploy branches never rebase. Then try the hybrid for one feature: rebase your branch onto main, clean it with interactive rebase, and merge it with --no-ff. Compare the resulting graph with your last merged feature. If the linear version is easier to review and bisect — it usually is — you have your workflow. The question was never which command is better. It is who else is standing on the branch.
References
Comments
More in Web Development
What Is Rendezvous and Proximity Operations? (Cosmos 2612)
What is rendezvous and proximity operations? Cosmos 2612 flew one against a US satellite, closing to 500 meters — the closest unconsented rendezvous ever seen.
Read more